
KasperSkytte/snakemake_savont


Minimalistic amplicon workflow for ONT data with ASVs generated by savont
Overview
Latest release: v2.0.1, Last update: 2026-11-02
Share link: https://snakemake.github.io/snakemake-workflow-catalog?wf=KasperSkytte/snakemake_savont
Quality control: linting: passed formatting: passed
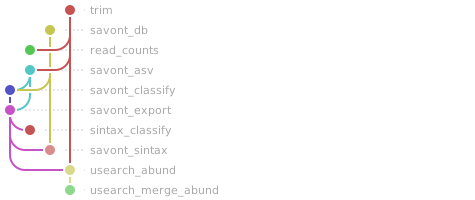
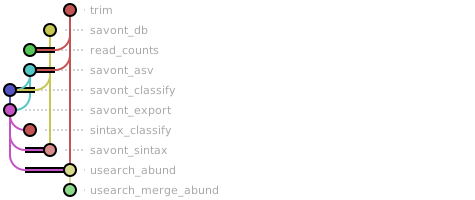
Workflow Rule Graph
This visualization of the workflow’s rule graph was automatically generated using Snakevision
Deployment
Step 1: Install Snakemake and Snakedeploy
Snakemake and Snakedeploy are best installed via the Conda package manager. It is recommended to install conda via Miniforge. Run
conda create -c conda-forge -c bioconda -c nodefaults --name snakemake snakemake snakedeploy
to install both Snakemake and Snakedeploy in an isolated environment. For all following commands ensure that this environment is activated via
conda activate snakemake
For other installation methods, refer to the Snakemake and Snakedeploy documentation.
Step 2: Deploy workflow
With Snakemake and Snakedeploy installed, the workflow can be deployed as follows. First, create an appropriate project working directory on your system and enter it:
mkdir -p path/to/project-workdir
cd path/to/project-workdir
In all following steps, we will assume that you are inside of that directory. Then run
snakedeploy deploy-workflow https://github.com/KasperSkytte/snakemake_savont . --tag v2.0.1
Snakedeploy will create two folders, workflow and config. The former contains the deployment of the chosen workflow as a Snakemake module, the latter contains configuration files which will be modified in the next step in order to configure the workflow to your needs.
Step 3: Configure workflow
To configure the workflow, adapt config/config.yml to your needs following the instructions below.
Step 4: Run workflow
The deployment method is controlled using the --software-deployment-method (short --sdm) argument.
To run the workflow with automatic deployment of all required software via conda/mamba, use
snakemake --cores all --sdm conda
To run the workflow using apptainer/singularity, use
snakemake --cores all --sdm apptainer
Snakemake will automatically detect the main Snakefile in the workflow subfolder and execute the workflow module that has been defined by the deployment in step 2.
For further options such as cluster and cloud execution, see the docs.
Step 5: Generate report
After finalizing your data analysis, you can automatically generate an interactive visual HTML report for inspection of results together with parameters and code inside of the browser using
snakemake --report report.zip
Configuration
The following section is imported from the workflow’s config/README.md.
Configuration
The configuration file config.yaml is used to set various options used throughout the workflow.
Option |
Default value |
Description |
|---|---|---|
|
|
The input folder is expected to contain a subfolder for each sampleID/barcode, in which all fastq files ( |
|
|
Folder for the results. |
|
|
Folder for temporary files, which are deleted after a succesful run. |
|
|
Folder for logs for each rule. |
|
|
Max number of threads to use for any individual rule. |
|
|
Max memory (MB) to request for any individual job. Memory is estimated from the input size and increased when a job is retried. |
|
|
|
|
|
Options passed on to |
|
|
Samples with fewer reads after trimming are left out of ASV generation (savont fails on samples with almost no reads). |
|
|
Options passed on to the |
|
|
Whether to classify the ASVs using |
|
|
Path to a savont database folder for |
|
|
Options passed on to the |
|
|
Whether to classify the ASVs using |
|
|
Path to the taxonomic reference database in SINTAX format (fasta or |
|
|
Options passed on to the |
|
|
Whether to classify the ASVs using |
|
|
Options passed on to the |
|
|
Whether to also estimate ASV abundances by mapping the trimmed reads of each sample to the ASVs using |
Have a look in the .test directory for minimal example files.
Linting and formatting
Linting results
All tests passed!
Formatting results
All tests passed!