
loucerac/bps-workflow


None
Overview
Latest release: v0.1.2, Last update: 2026-11-08
Share link: https://snakemake.github.io/snakemake-workflow-catalog?wf=loucerac/bps-workflow
Quality control: linting: failed formatting: passed
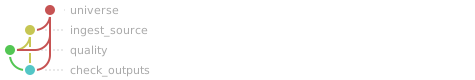
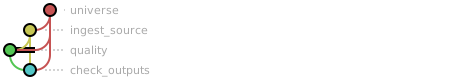
Workflow Rule Graph
This visualization of the workflow’s rule graph was automatically generated using Snakevision
Deployment
Step 1: Install Snakemake and Snakedeploy
Snakemake and Snakedeploy are best installed via the Conda package manager. It is recommended to install conda via Miniforge. Run
conda create -c conda-forge -c bioconda -c nodefaults --name snakemake snakemake snakedeploy
to install both Snakemake and Snakedeploy in an isolated environment. For all following commands ensure that this environment is activated via
conda activate snakemake
For other installation methods, refer to the Snakemake and Snakedeploy documentation.
Step 2: Deploy workflow
With Snakemake and Snakedeploy installed, the workflow can be deployed as follows. First, create an appropriate project working directory on your system and enter it:
mkdir -p path/to/project-workdir
cd path/to/project-workdir
In all following steps, we will assume that you are inside of that directory. Then run
snakedeploy deploy-workflow https://github.com/loucerac/bps-workflow . --tag v0.1.2
Snakedeploy will create two folders, workflow and config. The former contains the deployment of the chosen workflow as a Snakemake module, the latter contains configuration files which will be modified in the next step in order to configure the workflow to your needs.
Step 3: Configure workflow
To configure the workflow, adapt config/config.yml to your needs following the instructions below.
Step 4: Run workflow
The deployment method is controlled using the --software-deployment-method (short --sdm) argument.
To run the workflow with automatic deployment of all required software via conda/mamba, use
snakemake --cores all --sdm conda
Snakemake will automatically detect the main Snakefile in the workflow subfolder and execute the workflow module that has been defined by the deployment in step 2.
For further options such as cluster and cloud execution, see the docs.
Step 5: Generate report
After finalizing your data analysis, you can automatically generate an interactive visual HTML report for inspection of results together with parameters and code inside of the browser using
snakemake --report report.zip
Configuration
The following section is imported from the workflow’s config/README.md.
Configuration
Everything is in config/config.yaml, with a comment on each key, checked at
start-up against workflow/schemas/config.schema.yaml. An analysis workflow
importing this one as a module passes its own config, so these keys go in that
config too.
1. Point it at the delivery
delivery_root is the folder holding the delivery. It is a property of the
machine, so set it in a workflow profile, which Snakemake reads automatically:
mkdir -p profiles/default
cp profiles/default.example/config.yaml profiles/default/config.yaml
# edit:  delivery_root=/abs/path/to/the/delivery
profiles/default/ is gitignored. The run refuses to start if
delivery_root does not exist.
2. Describe the delivery
key |
what to set |
|---|---|
|
the people file: id, sex (and its labels in |
|
one entry per diagnosis file: id, date, ICD code, date format; optionally |
|
the delivery’s codes for “unknown”, and where month-precision dates land |
|
map ICD-9 records to ICD-10 with the CMS GEM |
|
the CSV encoding and memory bounds; these never change a result |
Set icd9_changeover only for a file where the ICD-9 → ICD-10 changeover was
measured: before it, V/E-led codes are read as ICD-9.
3. What to ingest
key |
what it decides |
|---|---|
|
records dated outside this window are not ingested |
|
optional: random person groups for a grouped bootstrap |
The test case in .test/config/config.yaml has the same keys, on the synthetic
delivery in .test/data.
Workflow parameters
The following table is automatically parsed from the workflow’s config.schema.y(a)ml file.
Parameter |
Type |
Description |
Required |
Default |
|---|---|---|---|---|
delivery_root |
string |
yes |
||
universe |
yes |
|||
. sex_values |
yes |
|||
sources |
yes |
|||
sentinels |
array |
yes |
||
mid_month_day |
integer |
yes |
||
map_icd9 |
boolean |
yes |
||
scale |
yes |
|||
. csv_block_mb |
number |
yes |
||
. batch_rows |
integer |
yes |
||
. person_batch |
integer |
yes |
||
. pair_chunk |
integer |
yes |
||
records |
yes |
|||
. from |
string |
yes |
||
. to |
string |
yes |
||
buckets |
||||
. n |
integer |
yes |
||
. seed |
integer |
yes |
Linting and formatting
Linting results
1/home/runner/work/snakemake-workflow-catalog/snakemake-workflow-catalog/.pixi/envs/default/lib/python3.13/site-packages/google/auth/transport/grpc.py:43: FutureWarning: grpcio < 1.83.0 does not support Post-Quantum Cryptography (PQC). Support for non-PQC environments is deprecated. In April 2027, google-auth will raise its minimum requirements to enforce grpcio >= 1.83.0. For more details on Google Cloud's post-quantum security migration, visit: https://cloud.google.com/security/resources/post-quantum-cryptography
2  warnings.warn(
3WorkflowError in file "/tmp/tmp0q3r2_yn/loucerac-bps-workflow-b4fffc4/workflow/rules/common.smk", line 11:
4delivery_root 'data/raw/20260903' does not exist (resolved from /tmp/tmp0q3r2_yn/loucerac-bps-workflow-b4fffc4). Set it in config/config.yaml or, per machine, in profiles/default/config.yaml (copy profiles/default.example/).
5  File "/tmp/tmp0q3r2_yn/loucerac-bps-workflow-b4fffc4/workflow/rules/common.smk", line 11, in <module>
Formatting results
All tests passed!